定义 str = [s, n] 表示 str 由 n 个字符串 s 连接构成。
例如,str == ["abc", 3] =="abcabcabc" 。
如果可以从 s2 中删除某些字符使其变为 s1,则称字符串 s1 可以从字符串 s2 获得。
例如,根据定义,s1 = "abc" 可以从 s2 = "ab _ **dbe**_ c" 获得,仅需要删除加粗且用斜体标识的字符。
现在给你两个字符串 s1 和 s2 和两个整数 n1 和 n2 。由此构造得到两个字符串,其中 str1 = [s1, n1]、str2 = [s2, n2] 。
请你找出一个最大整数 m ,以满足 str = [str2, m] 可以从 str1 获得。
示例 1:
**输入:** s1 = "acb", n1 = 4, s2 = "ab", n2 = 2
**输出:** 2
示例 2:
**输入:** s1 = "acb", n1 = 1, s2 = "acb", n2 = 1
**输出:** 1
提示:
1 <= s1.length, s2.length <= 100s1 和 s2 由小写英文字母组成1 <= n1, n2 <= 106
📺 视频题解
📖 文字题解 方法一:找出循环节 思路
由于题目中的 n1 和 n2 都很大,因此我们无法真正把 S1 = [s1, n1] 和 S2 = [s2, n2] 都显式地表示出来。由于这两个字符串都是不断循环的,因此我们可以考虑找出 S2 在 S1 中出现的循环节,如果我们找到了循环节,那么我们就可以很快算出 S2 在 S1 中出现了多少次了。
有些读者可能对循环节这个概念会有些陌生,这个概念我们可以类比无限循环小数,如果从小数部分的某一位起向右进行到某一位止的一节数字「循环」出现,首尾衔接,称这种小数为「无限循环小数」,这一节数字称为「无限循环小数」。比如对于 3.56789789789... 这个无限循环小数,它的小数部分就是以 789 为一个「循环节」在无限循环,且开头可能会有部分不循环的部分,这个数字中即为 56。
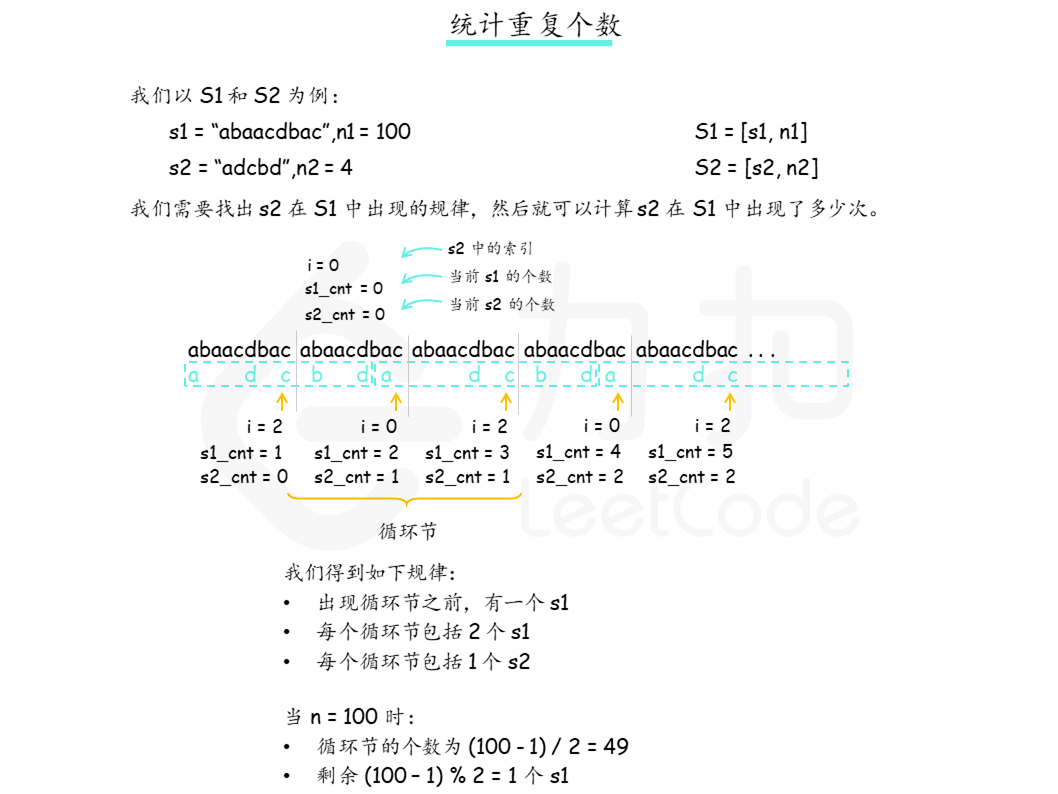
那么回到这题,我们可以将不断循环的 s2 组成的字符串类比作上面小数部分,去找是否存在一个子串,即「循环节」,满足不断在 S2 中循环,且这个循环节能对应固定数量的 s1 。如下图所示,在第一次出现后,S2 的子串 bdadc 构成一个循环节:之后 bdadc 的每次出现都需要有相应的两段 s1。
当我们找出循环节后,我们即可知道一个循环节内包含 s1 的数量,以及在循环节出现前的 s1 的数量,这样就可以在 $O(1)$ 的时间内,通过简单的运算求出 s2 在 S1 中出现的次数了。当然,由于 S1 中 s1 的数量 n1 是有限的,因此可能会存在循环节最后一个部分没有完全匹配,如上图最后会单独剩一个 s1 出来无法完全匹配完循环节,这部分我们需要单独拿出来遍历处理统计。
有些读者可能会怀疑循环节是否一定存在,这里我们给出的答案是肯定的,根据鸽笼原理 ,我们最多只要找过 |s2| + 1 个 s1,就一定会出现循环节。
算法
我们设计一个哈希表 recall :哈希表 recall 以 s2 字符串的下标 index 为索引,存储匹配至第 s1cnt 个 s1 的末尾,当前匹配到第 s2cnt 个 s2 中的第 index 个字符时, 已经匹配过的s1 的个数 s1cnt 和 s2 的个数 s2cnt 。
我们在每次遍历至 s1 的末尾时根据当前匹配到的 s2 中的位置 index 查看哈希表中的对应位置,如果哈希表中对应的位置 index 已经存储元素,则说明我们找到了循环节。循环节的长度可以用当前已经匹配的 s1 与 s2 的数量减去上次出现时经过的数量(即哈希表中存储的值)来得到。
然后我们就可以通过简单的运算求出所有构成循环节的 s2 的数量,对于不参与循环节部分的 s1,直接遍历计算即可,具体实现以及一些细节边界的处理请看下文的代码。
[sol1-Python3] 1 2 3 4 5 6 7 8 9 10 11 12 13 14 15 16 17 18 19 20 21 22 23 24 25 26 27 28 29 30 31 32 33 34 35 36 37 38 39 40 41 42 43 44 45 46 47 48 49 50 class Solution : def getMaxRepetitions (self, s1: str , n1: int , s2: str , n2: int ) -> int : if n1 == 0 : return 0 s1cnt, index, s2cnt = 0 , 0 , 0 recall = dict () while True : s1cnt += 1 for ch in s1: if ch == s2[index]: index += 1 if index == len (s2): s2cnt, index = s2cnt + 1 , 0 if s1cnt == n1: return s2cnt // n2 if index in recall: s1cnt_prime, s2cnt_prime = recall[index] pre_loop = (s1cnt_prime, s2cnt_prime) in_loop = (s1cnt - s1cnt_prime, s2cnt - s2cnt_prime) break else : recall[index] = (s1cnt, s2cnt) ans = pre_loop[1 ] + (n1 - pre_loop[0 ]) // in_loop[0 ] * in_loop[1 ] rest = (n1 - pre_loop[0 ]) % in_loop[0 ] for i in range (rest): for ch in s1: if ch == s2[index]: index += 1 if index == len (s2): ans, index = ans + 1 , 0 return ans // n2
[sol1-C++] 1 2 3 4 5 6 7 8 9 10 11 12 13 14 15 16 17 18 19 20 21 22 23 24 25 26 27 28 29 30 31 32 33 34 35 36 37 38 39 40 41 42 43 44 45 46 47 48 49 50 51 52 53 54 55 56 57 58 59 60 61 62 63 64 65 66 class Solution {public : int getMaxRepetitions (string s1, int n1, string s2, int n2) if (n1 == 0 ) { return 0 ; } int s1cnt = 0 , index = 0 , s2cnt = 0 ; unordered_map<int , pair<int , int >> recall; pair<int , int > pre_loop, in_loop; while (true ) { ++s1cnt; for (char ch: s1) { if (ch == s2[index]) { index += 1 ; if (index == s2.size ()) { ++s2cnt; index = 0 ; } } } if (s1cnt == n1) { return s2cnt / n2; } if (recall.count (index)) { auto [s1cnt_prime, s2cnt_prime] = recall[index]; pre_loop = {s1cnt_prime, s2cnt_prime}; in_loop = {s1cnt - s1cnt_prime, s2cnt - s2cnt_prime}; break ; } else { recall[index] = {s1cnt, s2cnt}; } } int ans = pre_loop.second + (n1 - pre_loop.first) / in_loop.first * in_loop.second; int rest = (n1 - pre_loop.first) % in_loop.first; for (int i = 0 ; i < rest; ++i) { for (char ch: s1) { if (ch == s2[index]) { ++index; if (index == s2.size ()) { ++ans; index = 0 ; } } } } return ans / n2; } };
[sol1-Java] 1 2 3 4 5 6 7 8 9 10 11 12 13 14 15 16 17 18 19 20 21 22 23 24 25 26 27 28 29 30 31 32 33 34 35 36 37 38 39 40 41 42 43 44 45 46 47 48 49 50 51 52 53 54 55 56 57 58 59 60 61 62 63 64 65 66 67 68 69 70 class Solution { public int getMaxRepetitions (String s1, int n1, String s2, int n2) { if (n1 == 0 ) { return 0 ; } int s1cnt = 0 , index = 0 , s2cnt = 0 ; Map<Integer, int []> recall = new HashMap <Integer, int []>(); int [] preLoop = new int [2 ]; int [] inLoop = new int [2 ]; while (true ) { ++s1cnt; for (int i = 0 ; i < s1.length(); ++i) { char ch = s1.charAt(i); if (ch == s2.charAt(index)) { index += 1 ; if (index == s2.length()) { ++s2cnt; index = 0 ; } } } if (s1cnt == n1) { return s2cnt / n2; } if (recall.containsKey(index)) { int [] value = recall.get(index); int s1cntPrime = value[0 ]; int s2cntPrime = value[1 ]; preLoop = new int []{s1cntPrime, s2cntPrime}; inLoop = new int []{s1cnt - s1cntPrime, s2cnt - s2cntPrime}; break ; } else { recall.put(index, new int []{s1cnt, s2cnt}); } } int ans = preLoop[1 ] + (n1 - preLoop[0 ]) / inLoop[0 ] * inLoop[1 ]; int rest = (n1 - preLoop[0 ]) % inLoop[0 ]; for (int i = 0 ; i < rest; ++i) { for (int j = 0 ; j < s1.length(); ++j) { char ch = s1.charAt(j); if (ch == s2.charAt(index)) { ++index; if (index == s2.length()) { ++ans; index = 0 ; } } } } return ans / n2; } }
复杂度分析